P.S: This is a quick reaction to the publication of the DEPA framework for AI Training. More details will follow and a discussion paper will be submitted by Naavi (as an individual) at the IDPS 2026 at bangalore on November 21.
The Ministry of Electronics and Information Technology (MeitY) has released a discussion draft titled Data Empowerment and Protection Architecture (DEPA) for AI Training – A National Framework for Data Empowered Ecosystems for Shaping the Age of AI.
The proposal no doubt deserves serious attention. India needs access to large, diverse and representative datasets if it is to develop AI systems that reflect Indian realities. Valuable datasets exist across hospitals, banks, educational institutions, government agencies and commercial organisations. However, these datasets are fragmented, and institutions are often reluctant to share them because of privacy risks, confidentiality obligations, security concerns and regulatory uncertainty.
The proposed DEPA architecture seeks to address this problem through Data Exchange Platforms, Secure Data Environments, electronic contracts, Differential Privacy and an institutional governance mechanism.
At first sight, this appears to be a progressive techno-legal solution. It aims to facilitate AI training without necessarily transferring raw datasets to AI developers. It envisages controlled access, privacy-enhancing technologies and contractual restrictions on the use of contributed data.
However, two fundamental questions need to be asked.
First, does the ability to share data securely automatically create the legal authority to share and process that data?
Second, does making Indian datasets available through this architecture necessarily strengthen India’s AI sovereignty, or could it allow foreign-controlled entities to capture the strategic and economic value of Indian data?
My concern is that the DEPA proposal, in its present form, does not adequately address either question.
The problem is not the objective of DEPA. India certainly needs a national data-sharing architecture. The problem is the possibility of treating a data-sharing architecture as a substitute for a data-protection compliance architecture, while simultaneously failing to protect the national interest in the value generated from Indian datasets.
This could expose both society and individual Data Fiduciaries to significant risks.
1. Data availability is not data-use authority
The DEPA document identifies what it calls the “Data Deadlock”. Valuable datasets exist across sectors, but organisations are reluctant to share them because of privacy, security, confidentiality and regulatory concerns.
The proposed solution is to bring Training Data Providers (TDPs) and Training Data Consumers (TDCs) into a common techno-legal ecosystem.
Hospitals, banks and public agencies may become TDPs. AI developers, start-ups, researchers and enterprises may become TDCs.
But where does the legal authority for the original Data Fiduciary to make this data available come from?
Under the Digital Personal Data Protection Act, 2023 (DPDPA), processing of personal data must be supported by a ground recognised under Section 4, read with Sections 5, 6 and 7, as applicable.
The fact that the intended recipient is a registered participant in DEPA does not create an additional ground for processing.
The DPDPA does not recognise a general-purpose ground called “AI innovation”. Nor does it provide a blanket permission to use personal data for AI training merely because the proposed training may ultimately benefit society.
A bank may possess millions of transaction records. A hospital may possess years of patient records. A school may have detailed information about students. Possession of these records does not confer an unrestricted right to contribute them to a national or international AI training ecosystem.
The Data Fiduciary must first determine whether the proposed processing is lawful.
This includes answering questions such as:
-
- Was the data collected for a purpose that covers the proposed AI training?
- Does the original notice adequately describe that purpose?
- Is consent required, and if so, has valid consent been obtained?
- Can a specific legitimate use under Section 7 be established?
- Is any applicable statutory exemption actually available?
- Are there restrictions under other applicable laws, contractual obligations or sectoral regulations?
These questions cannot be answered by a data exchange platform.
DEPA can facilitate data access. It cannot manufacture a lawful basis for processing.
2. The pseudonymisation and anonymisation confusion
One of the most important issues in the DEPA document is the treatment of anonymisation.
The document correctly recognises that removing direct identifiers such as names, addresses and identification numbers is not sufficient to prevent re-identification. It discusses the possibility of linking multiple datasets and identifying individuals through combinations of seemingly innocuous attributes.
It therefore proposes more sophisticated privacy-preserving techniques, particularly Differential Privacy.
However, the document also refers to pseudonymised keys being retained by the originating agency while data is shared in a de-identified form.
This raises a crucial legal question.
If the originating agency retains the keys that enable the data to be linked back to an individual, can the shared information automatically be treated as non-personal data?
The answer cannot be assumed.
The DPDPA applies to digital personal data. The relevant issue is whether the information relates to an identifiable individual. Replacing a name with a code does not necessarily remove the possibility of identification.
Pseudonymisation is a security and privacy-enhancing technique. It is not necessarily anonymisation in the legal sense.
Consider a hospital contributing patient records to a DEPA-based health AI project. Names and mobile numbers are removed, but the records retain age, gender, admission dates, diagnosis, treatment details, hospital location and unusual medical conditions.
Even if the AI developer does not possess the identity key, the originating hospital may still be able to associate the records with identifiable patients. Other participants may also have access to auxiliary datasets capable of enabling re-identification.
The risk becomes greater when datasets from different hospitals, insurance companies, laboratories and public health agencies are combined.
The DEPA document itself recognises that combining multiple datasets can increase the possibility of identifying individuals. Yet the framework appears to place substantial reliance on the data provider’s responsibility to anonymise data before sharing.
This is not enough.
A Data Fiduciary cannot discharge its statutory responsibilities merely by declaring that its dataset has been anonymised. There must be a defensible assessment of identification risk, including the possibility of linkage with other datasets, the nature of the information, the technical capabilities of likely recipients and the consequences of re-identification.
A standardised DEPA certification of anonymisation, if introduced, should not become an automatic legal safe harbour.
3. Differential Privacy is not a substitute for lawful processing
The DEPA proposal gives considerable importance to Differential Privacy.
Differential Privacy is an important mathematical technique. It can reduce the ability to infer whether a particular individual’s information contributed to a statistical output or model.
The proposal also discusses privacy budgets to limit cumulative privacy loss resulting from repeated queries.
These are valuable technical safeguards. However, three separate questions must not be confused:
-
- Is the original collection and processing of personal data lawful?
- Is the transformation and use of the data sufficiently privacy-preserving?
- Does the resulting model or output create risks to individuals?
Differential Privacy primarily addresses aspects of the second and third questions. It does not independently answer the first.
For example, suppose a bank collects customer transaction data for operating bank accounts and meeting regulatory requirements. The bank subsequently decides to contribute the transaction data to an AI training project.
Even if the data is subjected to Differential Privacy, the bank must still examine whether the proposed processing is supported by a lawful ground under the DPDPA.
The mathematical protection does not retrospectively validate an otherwise unauthorised purpose.
There is also a technical question concerning where Differential Privacy is applied. The protection available to an individual may depend on the precise implementation, the location at which noise is introduced, the privacy budget, the number of queries, the training method and the possibility of leakage through model outputs.
A statement that Differential Privacy is used is not, by itself, proof that privacy risk has been adequately controlled.
The implementation must be independently evaluated.
4. Purpose limitation: Can data collected for one purpose be used for another?
This is perhaps the most serious DPDPA issue for an individual Data Fiduciary.
The DPDPA requires processing to be based on a lawful purpose. Section 5 and the Digital Personal Data Protection Rules, 2025 require a Data Fiduciary to provide an appropriate notice describing the personal data and the purpose or purposes of processing.
Consider the following examples:
- A hospital collects patient data for diagnosis and treatment.
- A bank collects transaction information for operating accounts and providing financial services.
- An educational institution collects student information for academic administration.
- An insurance company collects claims information for claim assessment.
Can these organisations subsequently contribute the information to an AI training ecosystem?
The answer depends on the legal basis and the facts of the processing. It cannot be answered merely by saying that the proposed AI model will be useful to the sector.
A broad purpose such as “improving services” should not automatically be interpreted as authorisation for every future AI training activity.
A Data Fiduciary must examine whether the new purpose is adequately covered by the original notice and lawful basis, or whether a fresh legal basis and appropriate notice or consent are required.
There is a further difficulty. AI training is often not a single, clearly defined activity. The same dataset may be used to train several models, fine-tune existing models, validate algorithms, test competing products and develop commercial applications.
A general permission to contribute data to a training platform could therefore become a gateway to multiple downstream purposes that were never meaningfully explained to the Data Principal.
This creates a serious risk of purpose expansion.
The DEPA framework must not become a mechanism by which a Data Fiduciary converts a narrowly collected dataset into a reusable commercial resource without examining the legal basis for each relevant processing activity.
5. Consent: Who obtains it, for what purpose, and from whom?
The DEPA document introduces Data Collaboratives as intermediary institutions that may work with communities to aggregate, standardise and organise data. It also contemplates that they may be responsible for obtaining primary consent where applicable.
This raises several questions.
If a Data Principal gives consent to a hospital for treatment, can a Data Collaborative later treat that consent as permission for AI training?
If consent is obtained by a Data Collaborative, is the Data Collaborative acting as an agent of the hospital, a Data Processor, or an independent Data Fiduciary?
Who provides the notice required under the DPDPA?
Who enables withdrawal of consent?
What happens when the Data Principal withdraws consent after the data has already been incorporated into a training dataset?
These are not minor implementation details. They go to the heart of the DPDPA’s consent architecture.
The Act requires consent to be free, specific, informed, unconditional and unambiguous, with a clear affirmative action. Consent is purpose-specific.
The DEPA ecosystem must not create a situation in which consent is obtained once at the point of data collection and then treated as a permanent authorisation for an unlimited range of future AI applications.
A Data Principal may reasonably agree to the use of health information for research into a particular disease but may not agree to its use in an unrelated commercial profiling system.
The ability to withdraw consent is equally important. A framework that can ingest data into a training environment but cannot meaningfully respond to subsequent withdrawal creates an imbalance between the rights of individuals and the convenience of AI developers.
The research exemption under Section 17(2)(b) also requires careful consideration. It is subject to statutory conditions and prescribed standards. It should not be interpreted as a blanket exemption for all commercial AI training.
6. The difficult question of erasure after AI training
The DEPA framework envisages a lifecycle in which data is contributed, transformed, used for training, validated and eventually deployed through an AI model.
But what happens when a Data Principal exercises the right to erasure under Section 12 of the DPDPA?
Deleting the original record from the source database may be possible.
Deleting a copy from a Data Exchange Platform may also be possible.
But what about:
-
- The transformed dataset used for training;
- Intermediate training files;
- Checkpoints and model weights;
- Embeddings and derived representations;
- Validation datasets;
- Backup copies;
- Models already deployed to customers?
Can the model be shown not to retain or reveal personal data relating to the individual?
Can the individual’s contribution be removed from the model?
Must the model be retrained, fine-tuned or subjected to machine unlearning?
Who bears the cost of such action?
The DPDPA does not prescribe a universal technical method for removing an individual’s contribution from every trained AI model. Nor should one assume that erasure of the source record automatically erases its influence from the model.
The DEPA architecture must address this problem before data is contributed.
A Data Fiduciary should not enter into a data-sharing arrangement without understanding the consequences of withdrawal, erasure, retention and model reuse.
7. A Secure Data Environment is not a legal sanctuary
The DEPA document places great reliance on Secure Data Environments (SDEs). It proposes hardware-based secure enclaves, encryption, access controls, immutable logs and other security mechanisms.
These measures can significantly reduce the risk of unauthorised access and data leakage.
However, a Secure Data Environment does not make every activity conducted inside it lawful.
A legally unauthorised purpose remains unauthorised even when executed inside a secure enclave.
A model trained on personal data without a valid legal basis does not become lawful merely because the data never leaves the enclave.
Similarly, a secure environment cannot automatically resolve questions of inappropriate data selection, excessive data collection, unauthorised secondary use, inaccurate or incomplete data, discriminatory training data, inappropriate retention or unlawful disclosure of model outputs.
The distinction is simple:
Security controls protect the processing environment. Data protection law governs whether the processing should take place at all and under what conditions.
The DEPA framework needs to make this distinction explicit.
8. The Data Fiduciary cannot outsource its accountability to DEPA
The DEPA document proposes an ecosystem involving Data Principals, Data Collaboratives, Training Data Providers, Training Data Consumers, Data Exchange Platforms, Secure Data Environment providers, technology service providers and an oversight body.
This is a complex chain of responsibility.
The difficulty is that the DPDPA does not necessarily recognise all these roles as separate statutory categories.
The Act identifies Data Fiduciaries and Data Processors. A Data Fiduciary determines the purpose and means of processing, while a Data Processor processes personal data on behalf of a Data Fiduciary.
A participant cannot simply be labelled a Data Processor because the DEPA framework calls it a service provider.
For example, an AI developer who receives data and independently determines the purposes and means of training a commercial model may not be acting merely as a Data Processor on behalf of the originating institution.
Depending on the actual arrangement, it may be a separate Data Fiduciary.
Similarly, a Data Collaborative that aggregates data from several institutions, determines the purposes of aggregation or decides how the data will be used may have responsibilities that cannot be settled merely through its contractual designation.
Section 8(1) of the DPDPA places responsibility on the Data Fiduciary for compliance in respect of processing undertaken by it or on its behalf by a Data Processor. Section 8(2) also requires a valid contract for engagement of a Data Processor.
The statutory responsibility cannot be eliminated by an electronic contract stating that the platform, data exchange or AI developer will take care of compliance.
A contract can allocate operational duties and provide rights of indemnity. It cannot override statutory responsibility.
The DEPA framework must therefore identify, for each processing activity:
-
- Who determines the purpose?
- Who determines the essential means?
- Who acts on behalf of another entity?
- Who is an independent Data Fiduciary?
- Who is responsible for responding to Data Principal rights?
- Who is responsible for breach notification?
- Who is responsible for erasure and retention decisions?
Without this allocation, the framework risks creating an accountability vacuum.
9. Data sovereignty: Could DEPA become a gateway for foreign control over Indian data?
There is another important dimension of the DEPA proposal which deserves independent examination. This is the question of data sovereignty.
The document speaks of India’s ambition to develop its own AI ecosystem. At the same time, the proposed architecture is not expressly reserved for Indian AI developers.
Training Data Consumers may include start-ups, researchers and enterprises. The framework also envisages global collaboration, cross-border research and international data-sharing arrangements.
There is nothing inherently wrong with international collaboration. Science and technology advance through collaboration, and Indian institutions should be able to participate in global research.
But there is a fundamental distinction between India sharing data under conditions that preserve Indian control and India making its data available through an architecture in which foreign entities may acquire the economic and strategic benefits of that data without corresponding Indian control.
The DEPA draft does not establish a clear Indian ownership or nationality requirement for Training Data Consumers. Nor does it prescribe a comprehensive framework for retaining Indian control over the resulting models, derived intelligence and commercial value.
This is a significant omission.
The CIBIL experience: A lesson India should not ignore
India has already experienced a development in the credit information sector which should be remembered while designing a national data-sharing architecture.
The Credit Information Companies (Regulation) Act, 2005 (CICRA) created the statutory framework for credit information companies in India.
CIBIL was established in 2000, with participation from Indian financial institutions. It became a central institution in the collection and dissemination of credit information in the Indian financial system.
TransUnion, an international credit information company, initially participated as a technology, analytics and decision-services partner and shareholder. Over time, its shareholding increased. TransUnion’s corporate disclosures record that it obtained majority control of CIBIL in 2014 and subsequently increased its ownership to more than 90%.
Today, the institution operates as TransUnion CIBIL Limited.
This history is relevant not because one can automatically conclude that Indian credit information was illegally transferred abroad. Credit information companies operate within a statutory and regulatory framework, and credit information continues to be contributed by regulated Indian credit institutions.
The relevant lesson is different.
An institution established to serve an Indian national data requirement can, over time, come under the controlling ownership of a global information company.
The law may regulate the institution’s operations, access to information and security obligations. But the questions of who exercises corporate control, who owns the technology, who develops the analytical capabilities and who ultimately benefits commercially from the intelligence generated are separate matters.
The CIBIL experience demonstrates that the existence of an Indian regulatory framework does not, by itself, guarantee Indian ownership or strategic control over an institution handling nationally important information.
The CIBIL experience should therefore be treated as a warning when designing DEPA.
Could the same pattern emerge under DEPA?
Imagine that an Indian bank, hospital or government agency contributes a large dataset to a DEPA-enabled Data Exchange Platform.
The dataset is anonymised, encrypted and made available through a Secure Data Environment. A foreign AI company obtains access under an electronic contract and trains a sophisticated model.
The raw dataset may never leave India. The foreign company may not be permitted to download the original records.
But what happens to the intelligence generated from the data?
-
- Who owns the trained model?
- Who owns the intellectual property created through the training?
- Who controls the model weights and subsequent improvements?
- Can the model be commercially deployed in international markets?
- Can the model be used to develop products that compete with Indian companies?
- Can the resulting intelligence be transferred to a foreign parent company or affiliate?
- Can the foreign company use the experience and learning obtained from Indian datasets to develop models for other markets?
- What happens if the foreign company is acquired by another entity or its ownership changes?
These questions are not answered merely by ensuring that the raw data remains inside an Indian Secure Data Environment.
A trained model may embody considerable economic value derived from Indian data. It may contain patterns, correlations and sectoral intelligence which could not have been developed without access to that data.
The data may remain physically in India, but the value extracted from it may be owned, controlled and commercially exploited elsewhere.
This is a form of strategic data-value transfer that deserves attention even when there is no conventional cross-border transfer of raw personal data.
Data sovereignty is more than data localisation
It is important not to reduce data sovereignty to the question of whether a server is located in India.
Data localisation can help address certain jurisdictional and security concerns. But it does not necessarily preserve national control over the data ecosystem.
There are at least four dimensions:
- Physical control: Where is the original dataset stored and processed?
- Access control: Who can access the dataset and authorise its use?
- Intellectual property control: Who owns the model, algorithms and derived intellectual property created using the dataset?
- Economic control: Who receives the commercial benefits arising from the intelligence extracted from the data?
A framework that protects only the first two dimensions may still allow the strategic value of Indian data to migrate to foreign-controlled entities.
This is particularly important for healthcare, financial services, agriculture, education, geospatial information and public administration.
These datasets may contain insights about India’s population, consumption patterns, disease distribution, credit behaviour, agricultural productivity, geographical vulnerabilities and economic activity.
Such information has value beyond the immediate purpose for which it was collected. It may become a strategic national resource when combined and analysed at scale.
The DPDPA does not, by itself, guarantee data sovereignty
The DPDPA is a personal data protection law. It regulates the processing of digital personal data and imposes obligations on Data Fiduciaries and Data Processors.
It is not a comprehensive national data sovereignty law.
Section 16 provides for restrictions on transfers of personal data to countries or territories that may be notified by the Central Government, together with other applicable legal restrictions. It does not establish a general requirement that all personal data must remain within India.
Consequently, a Data Fiduciary should not assume that compliance with the DPDPA automatically ensures that the economic and strategic value of Indian data remains under Indian control.
There may also be datasets that are outside the scope of the DPDPA because they are genuinely anonymised or do not constitute personal data. Their commercial and strategic importance does not disappear merely because the DPDPA no longer applies to them.
This creates a policy gap.
The DPDPA protects individuals in relation to personal data. It does not, by itself, settle questions of national ownership, strategic control, intellectual property or the distribution of economic value generated from datasets.
DEPA must therefore address both personal data protection and the wider question of national data governance.
What safeguards should be incorporated?
I would suggest that the final DEPA framework explicitly address data sovereignty through the following safeguards:
1. Indian control over critical national datasets
Datasets relating to critical sectors such as banking, healthcare, public administration, national infrastructure and geospatial intelligence should have clearly defined access and control conditions. The conditions should not be left entirely to individual data providers.
2. Eligibility and scrutiny of foreign participants
Foreign entities may not be automatically excluded from collaboration. However, participation by foreign-controlled entities should be subject to appropriate ownership, beneficial ownership, jurisdiction and security scrutiny, particularly where strategically important datasets are involved.
3. Ownership and control of trained models
Every data-sharing contract should clearly specify who owns the resulting models, model weights, derived datasets, improvements and intellectual property. It should also address commercial exploitation outside India.
4. Restrictions on onward transfer and affiliate access
A foreign participant should not be permitted to transfer data, derived information, model artefacts or access rights to its parent company, subsidiaries, affiliates or other third parties without appropriate authorisation.
5. Indian jurisdiction and enforceability
Contracts should provide for enforceable Indian jurisdiction, audit access, regulatory cooperation, dispute resolution and remedies. A contractual promise should be backed by practical enforcement capability.
6. Governance of Data Exchange Platforms
The ownership and control of critical platforms should be disclosed. The framework should prescribe safeguards against concentration of control over national datasets, including arrangements for data portability, continuity, exit and independent audit.
7. Benefit-sharing
Where Indian datasets contribute materially to the development of commercially valuable AI models, the framework should consider mechanisms for ensuring that Indian institutions, data contributors and the Indian AI ecosystem receive a fair share of the resulting economic value.
8. Exit and change-of-control provisions
A change in ownership, control or jurisdiction of a platform or a major Training Data Consumer should trigger a review of existing data-sharing permissions and contracts.
These safeguards need not prevent international collaboration. They would ensure that collaboration takes place without India surrendering control over strategically important data assets.
10. Society-wide aggregation and collective profiling
The societal implications of DEPA may be even more serious than the compliance risk faced by individual institutions.
The proposal aims to combine data across sectors. This is precisely what makes it attractive for AI development.
But the combination of datasets also creates the possibility of profiling individuals and communities in ways that were not contemplated when the original data was collected.
Consider the possibility of combining banking transactions, health records, education records, geospatial information, insurance information and consumer behaviour.
Even if direct identifiers are removed, the combined information may reveal patterns about income, health, financial distress, social behaviour, location, employment and other aspects of individual life.
AI systems may learn correlations that are not obvious from any individual dataset.
Such models may subsequently be used to determine credit eligibility, insurance pricing, employment suitability, access to public services or other decisions affecting individuals.
This is a major societal concern.
The individual may never know that information originating from a hospital, bank or government department contributed to a model that later influenced a decision affecting that individual.
The fact that the training data was de-identified does not eliminate the need to examine the consequences of model deployment.
A national AI data ecosystem must therefore include safeguards against discriminatory profiling, group harms, inappropriate inference and misuse of model outputs.
11. Electronic contracts cannot replace statutory compliance
One of the interesting features of DEPA is the proposed use of machine-readable electronic contracts.
The document envisages contracts that specify permitted purposes, security requirements, access conditions and other restrictions. It also proposes technological enforcement of these conditions.
This is a welcome innovation.
However, a contract between a Training Data Provider and a Training Data Consumer is not a contract with every Data Principal whose personal data may be included in the dataset.
The Data Principal is not automatically bound by the data-sharing agreement.
Nor can the agreement extinguish the statutory rights of the Data Principal.
An electronic contract may establish that the AI developer has agreed not to use a dataset for an unauthorised purpose. But it does not establish that the original Data Fiduciary had the legal authority to share the data in the first place.
Similarly, an electronic contract may require the consumer to delete the data after a specified period. But the contract cannot determine the full extent of statutory retention obligations or eliminate a Data Principal’s rights.
The framework should distinguish between:
-
- The legal basis for processing personal data;
- The contractual conditions governing access and use;
- The technical controls enforcing those conditions;
- The accountability of each statutory Data Fiduciary.
These are four different layers of governance. They must work together, but one cannot replace another.
12. The proposed oversight body: A parallel compliance regime?
The DEPA document proposes an oversight body that may set standards, register participants, oversee data-sharing procedures and facilitate dispute resolution.
It also refers to the need for alignment with foundational laws such as the IT Act, 2000 and the DPDPA, 2023.
This raises an institutional question.
What exactly is the legal status of this oversight body?
Will it be a statutory regulator? A consortium? An industry self-regulatory organisation? A government-authorised platform operator? Or a combination of these?
The DPDPA establishes the Data Protection Board of India and assigns statutory functions to it. A DEPA oversight body cannot assume or displace the statutory powers of the Board merely by virtue of its role in the data-sharing ecosystem.
There is also a risk of regulatory confusion if a DEPA participant receives a certification from the oversight body and interprets that certification as proof of DPDPA compliance.
The proposed governance arrangement should clearly state that registration, certification, security audits and participation in the DEPA ecosystem do not constitute a statutory exemption or immunity under the DPDPA.
Otherwise, an organisation may have two different compliance assessments: one under the DEPA ecosystem and another under the DPDPA. A favourable result under the first could create unjustified confidence about the second.
13. Additional obligations for Significant Data Fiduciaries
The implications are particularly important for organisations that may be classified as Significant Data Fiduciaries (SDFs).
Banks, hospitals, insurance companies, large digital platforms and other institutions may process personal data at a scale or in a manner that attracts enhanced regulatory scrutiny.
Section 10 of the DPDPA imposes additional obligations on SDFs, including appointment of a Data Protection Officer and an independent data auditor, together with other prescribed measures.
The DPDPA Rules, 2025 also prescribe additional obligations relating to risk assessment, audit and other governance requirements for SDFs.
If an SDF contributes personal data to a DEPA-based AI training project, the decision should not be treated as an ordinary technology outsourcing activity.
The SDF must assess the entire processing chain, including:
-
- The legal basis for the contribution;
- The classification and sensitivity of the data;
- The risk of re-identification;
- The identity and statutory role of each participant;
- The security and privacy controls of the SDE;
- The possibility of model leakage;
- The contractual restrictions on downstream use;
- The ability to respond to Data Principal rights;
- The consequences of a breach or misuse;
- The ownership and control of the resulting models and derived intelligence.
The independent data auditor should be able to examine not merely the security certification of the platform but also the legal and governance basis for the SDF’s participation.
An SDF cannot defend a failure of its own statutory obligations by arguing that it relied on the DEPA platform or the certification of an external service provider.
14. What should a Data Fiduciary do before joining DEPA?
For the time being DEPA is unsafe for Data Fiduciaries and Data Fiduciaries are advised to keep themselves away from participation.
Before considering contributing any dataset containing personal data, the organisation should complete a structured legal and techno-legal assessment.
I would recommend the following minimum checks:
1. Data provenance assessment
Identify the original source of every dataset, the purpose for which it was collected, the applicable notice, the legal basis and any restrictions attached to the data.
2. Personal data classification
Determine whether the dataset contains digital personal data, pseudonymised data, genuinely anonymised information or a mixture of these categories.
3. Legal basis assessment
Establish the specific basis under Sections 4, 6 or 7 of the DPDPA, as applicable. Do not assume that AI training is automatically covered by the original purpose.
4. Role determination
Determine whether the organisation is acting as a Data Fiduciary, Data Processor or another participant in the proposed ecosystem. Examine the actual functions rather than relying on contractual labels.
5. Re-identification risk assessment
Examine the possibility of identification through linkage with other datasets. Assess the effectiveness of the proposed anonymisation and Differential Privacy techniques.
6. Contractual assessment
Ensure that agreements identify permitted purposes, prohibited uses, retention periods, onward-sharing restrictions, security obligations, audit rights, incident reporting and liability allocation.
7. Data Principal rights assessment
Establish how consent withdrawal, access, correction, erasure and grievance redressal will be handled throughout the data-sharing and AI training lifecycle.
8. Model risk assessment
Evaluate the possibility of personal data leakage, memorisation, inference, discriminatory outcomes and other adverse consequences arising from the trained model.
9. Security assessment
Evaluate the Secure Data Environment, encryption, access controls, privileged access, logging, monitoring, vulnerability management and incident response.
10. Sovereignty and value-retention assessment
Determine who controls the platform, who owns the trained model and its improvements, whether foreign affiliates can access derived information, and whether the Indian contributor retains appropriate rights and economic benefits.
11. Independent audit
Obtain an independent assessment of the legal, technical and organisational safeguards. For an SDF, this should be integrated with its statutory audit and governance responsibilities.
This assessment should be completed before the first dataset is transferred or made accessible to the ecosystem.
15. How DGPSI-AI and AIGSI can help address the gap
The DEPA proposal is primarily concerned with enabling data access and secure AI training. It is not a complete organisational compliance framework for the Data Fiduciary.
This is where an integrated approach to data governance and AI governance becomes necessary.
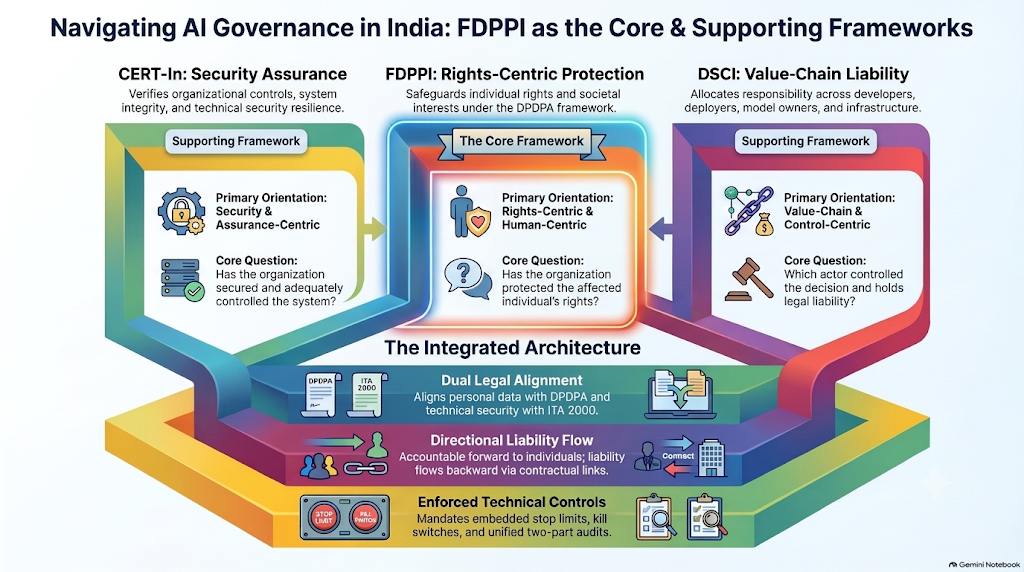
DGPSI-AI, developed as a techno-legal governance framework for AI deployers, can help an organisation examine the responsibilities that arise when it uses AI systems and processes personal data in the process.
The DEPA architecture can be considered as one of the external environments with which an organisation interacts. The organisation must still establish its own governance controls.
In particular, a Data Fiduciary participating in DEPA should be able to demonstrate:
-
- Accountability for the decision to contribute data;
- Identification of lawful purposes;
- Classification and valuation of data;
- Risk assessment before processing;
- Appropriate contractual and technical safeguards;
- Monitoring of AI training and deployment;
- Auditability and traceability;
- Responsibility for adverse consequences;
- Protection of national and institutional interests in data-derived value.
AIGSI, as a wider AI governance framework, can complement this by addressing the broader AI lifecycle, including risk management, accountability, fairness, transparency and responsible deployment.
The relationship should be understood as follows:
DEPA enables data sharing. DPDPA governs the lawful processing of personal data. DGPSI-AI supports organisational governance of AI-related processing. AIGSI addresses the wider governance of AI systems.
These are complementary functions, not substitutes.
16. What MeitY should correct before finalising the framework
The DEPA proposal is ambitious, but its final version should contain explicit safeguards on both statutory compliance and national data sovereignty.
I would recommend the inclusion of the following principle:
Participation in DEPA shall not, by itself, constitute a lawful basis for processing personal data under the DPDPA, nor shall registration, certification or use of a Secure Data Environment relieve any Data Fiduciary of its statutory obligations.
The framework should also require every Training Data Provider to document:
-
- Whether the dataset contains personal data;
- The legal basis for the proposed processing;
- The purpose for which the data is being made available;
- The assessment supporting any claim of anonymisation;
- The identity and legal role of each participant;
- The safeguards for responding to Data Principal rights;
- The responsibility for breach notification and remediation;
- The arrangements for retention, deletion and model-level risk management.
In addition, a separate data sovereignty policy should be incorporated into the architecture.
This should address:
-
- Ownership and beneficial ownership of critical platform operators;
- Eligibility and scrutiny of foreign-controlled participants;
- Control over access to strategically important Indian datasets;
- Ownership and commercial use of trained models and derived intelligence;
- Restrictions on onward transfer to foreign affiliates;
- Indian jurisdiction and enforceability;
- Change-of-control and exit arrangements;
- Benefit-sharing with Indian data contributors and the domestic AI ecosystem.
International collaboration should remain possible. But it should be governed by transparent conditions that protect individuals, Indian institutions and national interests.
Conclusion: India must not become merely a supplier of training data
India needs a national architecture for AI training. There is no disagreement about that.
The development of Indian AI models using Indian datasets can have enormous economic and social value. Healthcare, banking, education, agriculture and public administration can all benefit from the availability of representative datasets.
But the objective of making India data-rich for AI development must not lead to a situation in which individuals lose control over the lawful use of their personal data and Indian institutions lose control over the value generated from the data they contribute.
The DPDPA was enacted to recognise both the right of individuals to protect their personal data and the need to process such data for lawful purposes.
The balance is important.
The DEPA proposal has made a useful contribution by identifying technical mechanisms through which data can be shared and processed with reduced exposure. But its success must be judged not merely by the volume of data made available, the number of AI models trained or the economic value generated.
It must also be judged by whether the rights of individuals are protected, whether each Data Fiduciary can demonstrate compliance with the law, and whether India retains meaningful control over the strategic value of its data.
The CIBIL experience reminds us that an Indian institution handling nationally important information can, over time, come under foreign corporate control. The AI era creates a much larger opportunity for value extraction because the economic benefit may arise not only from the underlying data but also from the models, algorithms and intelligence developed using it.
There is a danger in allowing the convenience of a national data-sharing infrastructure to become a justification for weakening purpose limitation, consent, accountability and individual rights.
There is an equally serious danger in allowing India to provide the raw material for global AI development while the ownership and commercial benefits of the resulting intelligence accumulate elsewhere.
A Secure Data Environment may prevent a hacker from stealing a database. Differential Privacy may reduce the possibility of identifying an individual from model outputs. An electronic contract may restrict a recipient from using data for an unauthorised purpose.
But none of these measures can independently answer the fundamental legal question:
Was the Data Fiduciary entitled to use the individual’s personal data for this purpose in the first place?
And none of them answers the equally important national question:
Who will own, control and benefit from the intelligence created using Indian data?
These two questions must remain at the centre of India’s AI data governance architecture.
The danger is not merely that Indian personal data may be processed without adequate legal authority. The greater strategic danger is that India may supply the data, foreign entities may own the intelligence, and Indian society may be left paying for access to the AI capabilities created from its own data.
Data empowerment without data accountability is not data protection. Data sharing without data sovereignty may become data extraction.
Naavi
P.S: This note is being shared with iSpirit which is the brain behind this framework for their comments for discussion in the IDPS 2026 if available.